Detection vs. segmentation vs. alpha matting
Computer vision tools separate objects at different levels of precision. An object-detection model draws a rectangular bounding box around a region of interest, such as a face or product, without classifying individual outline pixels. A multi-class semantic segmentation model labels every pixel by category (such as person, car, or road), even when an object is in the background.
Automatic background removal relies on dichotomous image segmentation (DIS) and salient object detection. Instead of naming every object class in the scene, the model predicts a single continuous foreground mask: every pixel receives an opacity value from 0 (fully transparent background) to 255 (fully opaque foreground). Intermediate values between 1 and 254 create a soft alpha ramp that preserves anti-aliased edges, fabric weave, and fine hair strands.
Global context vs. local boundary detail
Every segmentation architecture balances two competing views of an image. Global context captures the overall scene structure—recognizing that a dark logo printed on a gray shirt belongs to the whole garment rather than floating alone. Local context traces high-frequency pixel transitions such as leaf tips, bicycle spokes, shoe soles, and stray hair.
When a model relies too heavily on local contrast, it may cut out a bright label and discard the rest of the product. When it relies only on coarse global features, it captures the rough silhouette but leaves webs of background trapped inside handles and narrow gaps.
| Model | Context strategy | Typical strength and limitation |
|---|---|---|
| U²-Net | Nested U-structure; evaluates multi-scale global and local context in a single pass. | Fast (~176 MB weights) and reliable on single-subject portraits, but can struggle on cluttered scenes with thin enclosed gaps. |
| IS-Net | Two-stage intermediate supervision: suppresses background globally first, then refines local boundaries. | Cleaner object outlines on noisy backgrounds (~179 MB weights), though unidirectional global-to-local flow can miss whole-object continuity on low-contrast parts. |
| BiRefNet | Bilateral Reference Network; passes context global-to-local and feeds edge refinements back into the global view. | Higher boundary accuracy on complex shapes and high-resolution edges by checking that local edges agree with the whole object, at the cost of heavier compute. |
| SAM (Segment Anything) | Promptable foundation model designed around input points, boxes, or masks. | Flexible for interactive multi-object selection, but unprompted single-pass background removal is slower and less specialized than dedicated saliency models. |
How segmentation accuracy is measured: IoU, Dice, and pixel accuracy
Researchers benchmark segmentation models against human-annotated ground-truth masks (such as DIS5K for complex objects and portrait datasets for people) using three primary formulas, where P is the set of predicted foreground pixels and G is the ground-truth foreground.
Intersection over Union (IoU, or the Jaccard index) divides the overlapping foreground pixels |P ∩ G| by the combined union |P ∪ G|. It is the strictest metric: leaving a halo of background pixels or clipping a strap penalizes the score immediately. The Sørensen–Dice coefficient computes 2|P ∩ G| / (|P| + |G|), weighting shared foreground pixels more heavily so it averages slightly higher than IoU on the same prediction.
Pixel accuracy—the percentage of all image pixels labeled correctly as either foreground or background—can be deceptive when the subject is small. Suppose a 1,000-pixel thumbnail contains 900 background pixels and 100 subject pixels. A broken model that labels 900 background pixels correctly and finds only 5 of the 100 subject pixels achieves 90.5% pixel accuracy ((900 + 5) / 1000), yet its IoU is just 5 / 100 = 0.05 and its Dice score is 10 / 105 = 0.095. For cutout quality, IoU and boundary F-scores matter far more than raw pixel accuracy.
| Metric | Formula | Score on this failure case |
|---|---|---|
| Pixel accuracy | (TP + TN) / Total = (5 + 900) / 1000 | 90.5% (looks high only because background dominates) |
| Sørensen–Dice | 2 × |P ∩ G| / (|P| + |G|) = 10 / 105 | 0.095 (correctly flags missing subject) |
| Intersection over Union (IoU) | |P ∩ G| / |P ∪ G| = 5 / 100 | 0.050 (strictly penalizes the missed 95% of the subject) |
Why models fail on specific regions—and how to diagnose yours
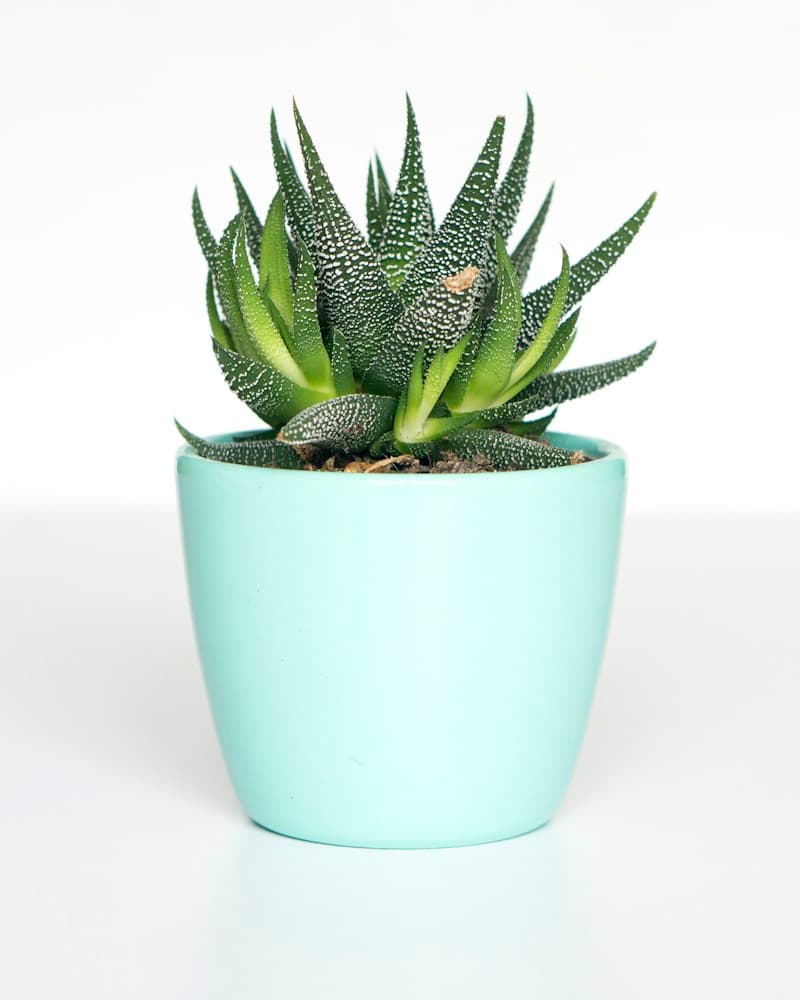
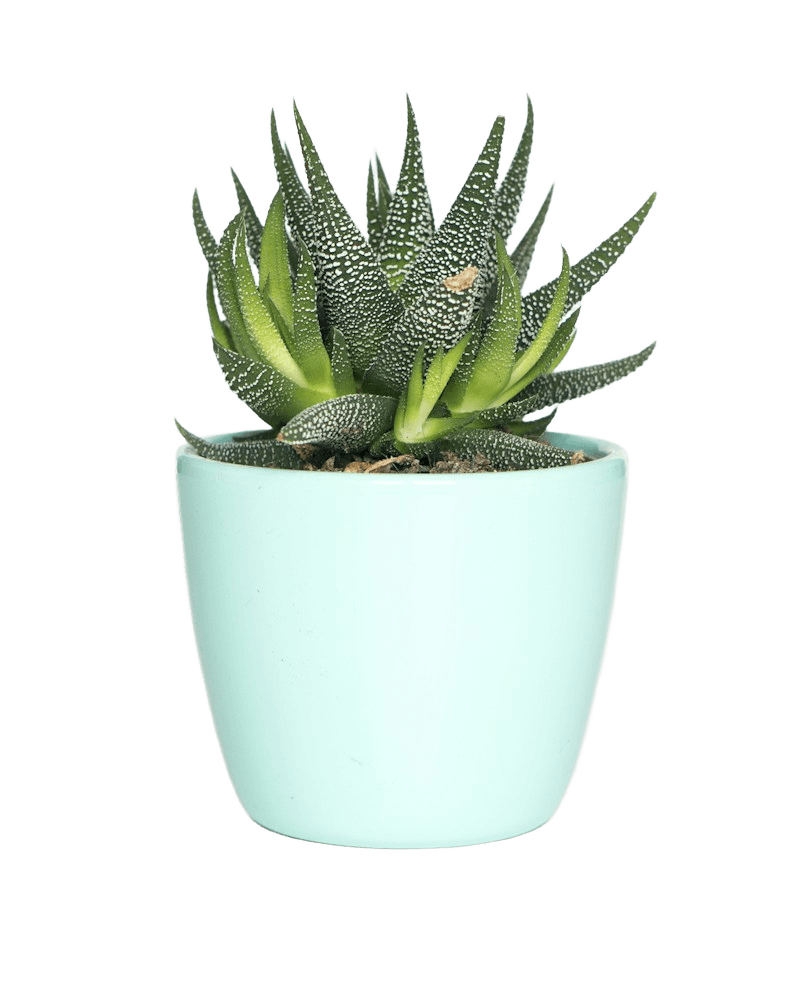
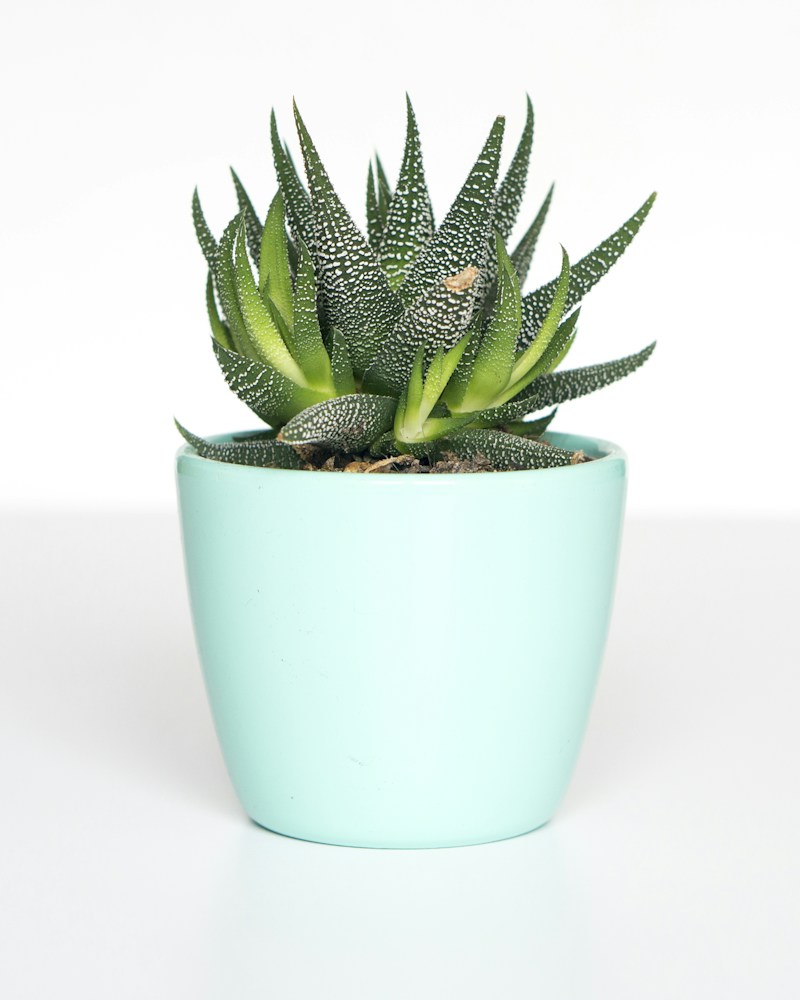
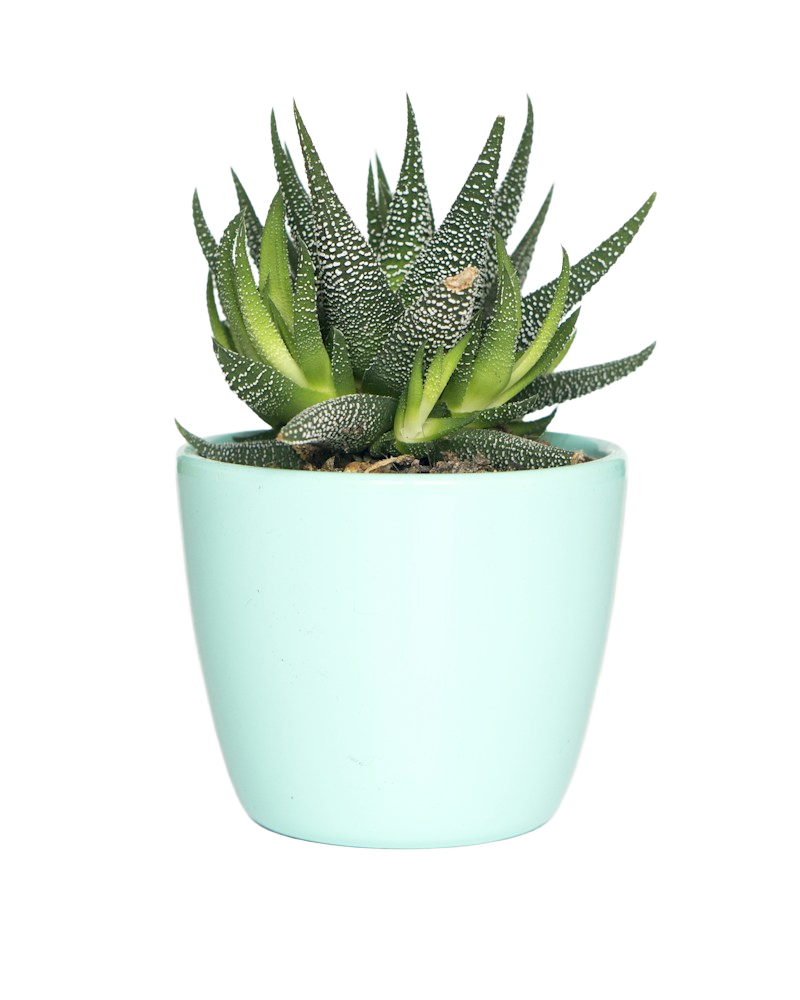
Understanding how a bidirectional saliency model works makes manual touch-ups faster. In the succulent sample above, inspect the V-shaped notches where two pointed leaves meet near the base. Because those background triangles are tiny and shadowed, a model's coarse pass can merge them into the plant. If the local refinement pass does not open them completely, a small triangle of dark backdrop remains.
Conversely, when a subject contains a region that matches the background tone—such as a white shoe sole on a white sweep or a pale label on glass—the local edge gradient drops near zero. If the global pass loses confidence there, a bite appears in the outline. Use Compare and the diagnostic steps below to separate mask errors from lighting artifacts:
- Switch between a pure white and a dark Charcoal background before touching the brush. Unwanted opaque patches stay visible on both; semi-transparent fringes shift appearance.
- Check enclosed interior spaces (pot rims, bag handles, bicycle spokes, and gaps between leaves). Use a small Erase brush to clear trapped background pockets.
- Check low-contrast perimeter segments where the subject's color matches the original backdrop. Use Restore area if the mask clipped a real edge.
- Distinguish alpha mask errors from color spill. If the edge geometry is accurate in Compare but carries a colored tint from the original room, erasing pixels only shrinks the object.